The Del-Bem Lab, at the Department of Genetics of the Luiz de Queiroz College of Agriculture (ESALQ/USP), studies how genomes evolve and how new biological functions arise at the molecular level. We combine comparative genomics, phylogenomics, pangenomics, transcriptomics, protein structure modelling and large-scale data analysis to reconstruct the history of genes, gene families and whole genomes, and to connect that history to biological function.
Plants and algae are at the heart of the lab, but our questions are deliberately broad. Gene duplication, horizontal gene transfer, gene loss, neofunctionalization, de novo gene birth and genome expansion shape the evolution of algae and land plants, but also of fungi and their mitochondria, giant viruses, bacteriophages and viruses that infect humans. Studying these systems side by side helps us separate lineage-specific innovations from general principles of genome evolution.
Research at a glance
- Plant terrestrialization and the evolution of Archaeplastida
- Cell walls, carbohydrate-active enzymes and soils
- Horizontal gene transfer and the origin of molecular novelty
- Mineral nutrition: how plants acquire iron
- Gene family evolution and neofunctionalization
- Genome architecture, non-coding RNAs and epigenetic variation
- Crop genomes: sugarcane and bioenergy plants
- Viral genome evolution: giant viruses, phages and SARS-CoV-2
- Organelle genomes: the dynamic mitochondria of fungi
- Computational tools and genomic resources
Plant terrestrialization and the evolution of Archaeplastida
Land plants transformed the surface of the Earth. As the dominant primary producers on land, they reshaped atmospheric chemistry, soils, freshwater systems and the evolution of animals. One of our central questions is how green plants became terrestrial organisms, and in particular which genomic changes accompanied the transition from streptophyte algae, the closest algal relatives of land plants, to the first embryophytes.
We work across the whole Archaeplastida supergroup (red algae, glaucophytes, chlorophyte and streptophyte green algae, and land plants), typically comparing dozens to hundreds of genomes. A recurring result of our work is that many toolkits regarded as typical of land plants were assembled earlier than expected, in aquatic or subaerial algae, as pre-adaptations to life on land. This is the case for part of the xyloglucan cell wall machinery and for the archetypal IRT iron transporters of flowering plants. Other key components were added much later, sometimes through horizontal gene transfer from bacteria and fungi. Explaining this mosaic of old and new parts is central to understanding how plants colonized land and diversified.
Cell walls, carbohydrate-active enzymes and soils
The plant cell wall is one of the most important innovations in the evolution of green plants. It is a structural component, but also a dynamic interface that mediates growth, water relations, defense, interactions with microorganisms and the physical contact between plants and soils. The lab has a long-standing interest in the evolution of the enzymes that synthesize, remodel and degrade cell wall polysaccharides.
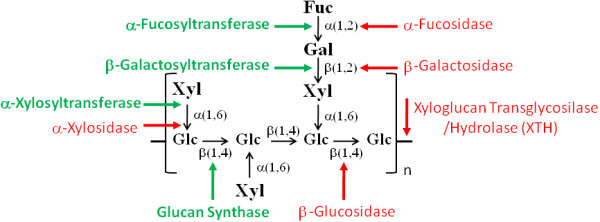
Our comparative analyses of xyloglucan-related genes indicated that part of the land plant xyloglucan machinery evolved in an aquatic environment, before land colonization, supporting the idea that a primordial xyloglucan-like polymer emerged in streptophyte algae as a pre-adaptation that allowed plants to colonize terrestrial habitats (Del Bem & Vincentz 2010). We later showed that a complex xyloglucan genetic machinery is present in most groups of charophycean green algae, and discussed xyloglucan evolution in the light of early soil formation, since xyloglucan released by roots and rhizoids acts as a potent soil aggregator (Del-Bem 2018).
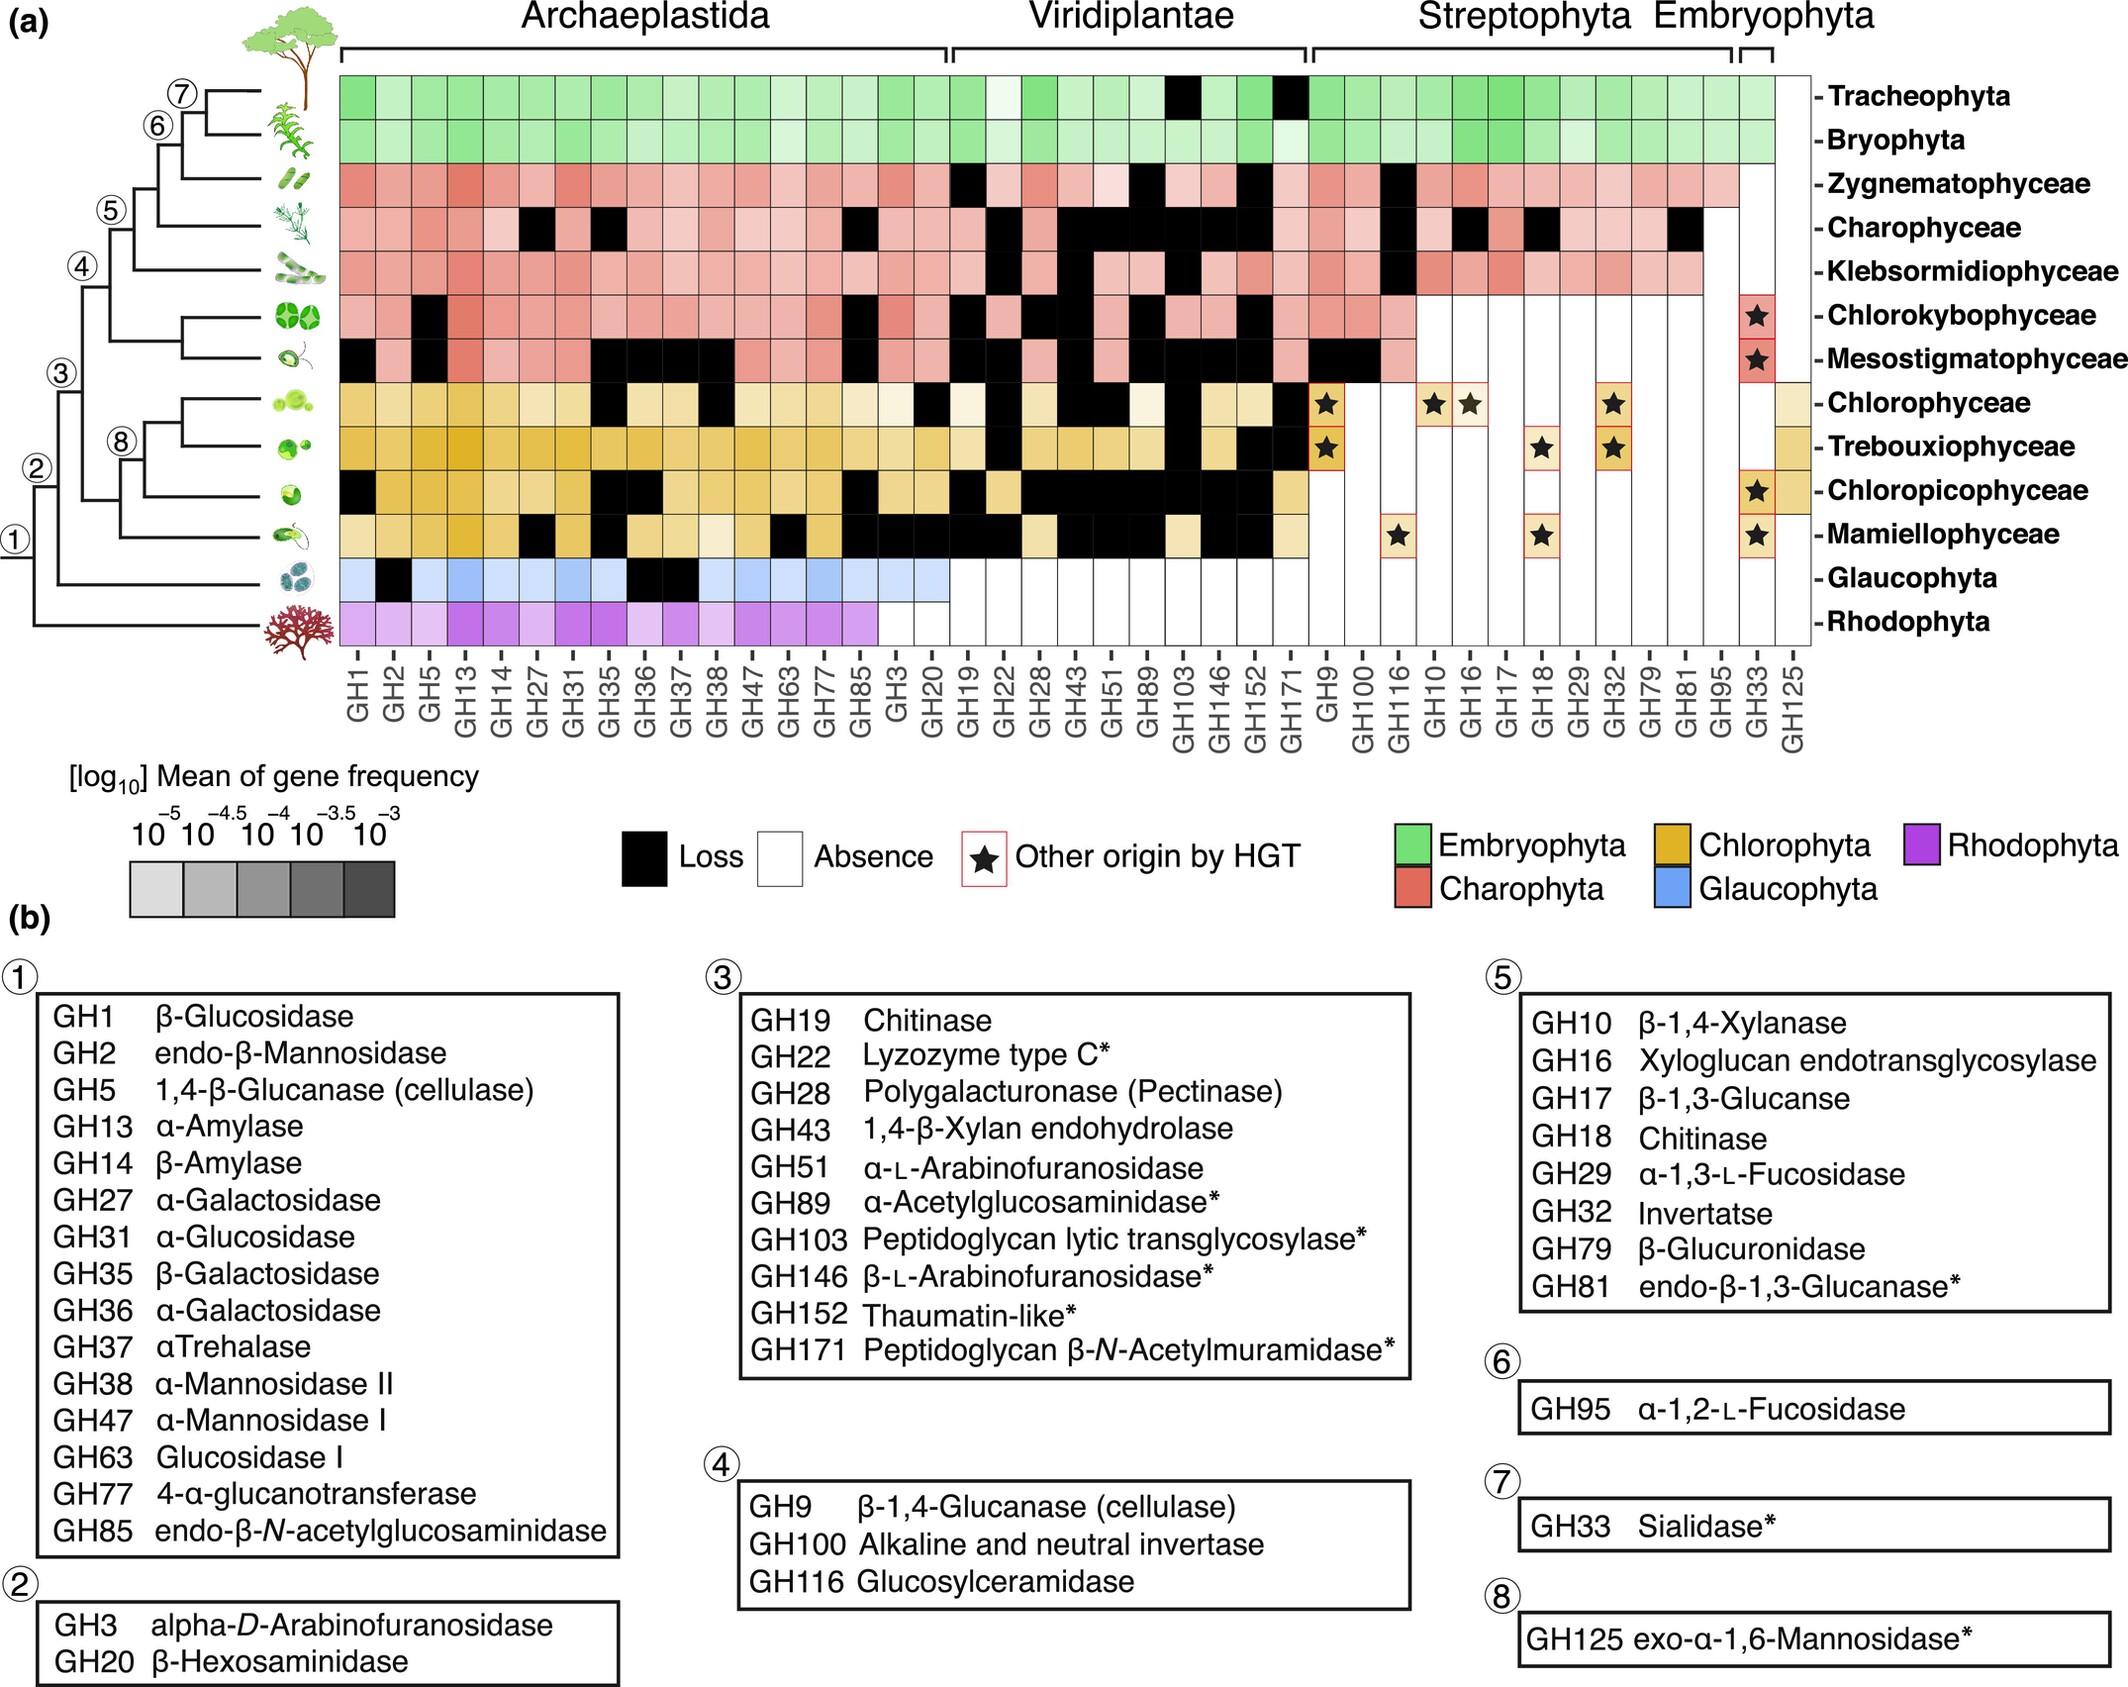
We then expanded this framework to the full repertoire of plant glycosyl hydrolases (GHs), enzymes that break down carbohydrates during reserve mobilization, pathogen defense and cell wall remodelling. The GH repertoire expanded from a few tens of genes in early archaeplastidians to more than 400 genes in modern angiosperms, spanning 40 GH families in land plants. We identified at least 23 GH families acquired by green plants through multiple horizontal gene transfer events, primarily from bacteria and fungi, and a significant shift in the subcellular localization of GH activity, with a marked increase in extracellular-targeted GH proteins associated with the diversification of cell wall polysaccharides and defense mechanisms against pathogens (Kfoury et al. 2024, New Phytologist, with collaborators at Michigan State University).
Our interest in carbohydrate metabolism also reaches plant physiology, from the mobilization of storage xyloglucan during seedling development of the rainforest tree Hymenaea courbaril to the genes associated with sucrose content in sugarcane.
Horizontal gene transfer and the origin of molecular novelty
A major theme in the lab is the origin of novelty: how new genes and gene families become integrated into pre-existing biological systems. Rather than treating horizontal gene transfer (HGT) as an evolutionary curiosity, we investigate it as a recurrent source of biochemical innovation in eukaryotes and viruses. Recent examples from our work include:
- at least 23 glycosyl hydrolase families acquired by green plants from bacteria and fungi (Kfoury et al. 2024);
- nicotianamine synthase, a key enzyme of chelation-based iron uptake, acquired from fungi through independent HGT events into euphyllophytes and specific moss lineages (de Campos et al. 2026, preprint);
- long non-coding RNA sequences with phylogenetic signatures of horizontal transfer in parasitic plants, particularly in Sapria (Rodrigues et al. 2024, preprint);
- accessory elements such as homing endonuclease genes shared between distantly related fungi in their mitochondrial genomes (Araujo et al. 2021);
- the first major vault proteins described in viruses, identified in bacteriophages from the human gut and phylogenetically close to bacterial homologs (Santos et al. 2023, preprint).
These cases raise broader questions that guide our work. Why do some gene families expand dramatically while others remain constrained? Why do some newly acquired genes become central to cellular functions, whereas others are rapidly lost? Which genomic, ecological and biochemical conditions favor the retention of foreign genes?
Mineral nutrition: how plants acquire iron
Life on land created new nutritional problems. Iron is essential for photosynthesis and many other processes, but it is generally found in the poorly soluble ferric form, and its availability depends strongly on soil chemistry. Plants solve this with two canonical mechanisms: reduction-based uptake (Strategy I) and chelation-based uptake (Strategy II), the latter characteristic of grasses. We reconstruct how both systems evolved.
Using 51 genomes of diverse Archaeplastida lineages, we found that iron is acquired through deeply divergent ZIP proteins in land plants and in chlorophyte green algae, indicating that ferrous iron uptake via ZIP transporters evolved independently at least twice during green plant evolution. The archetypal IRT proteins of angiosperms likely emerged before the origin of land plants, during early streptophyte algae terrestrialization (Rodrigues et al. 2023, New Phytologist).
For Strategy II, our ongoing work reveals a pronounced temporal uncoupling between its two core gene families: Yellow Stripe-Like (YSL) transporters most likely originated early in Viridiplantae and represent the deepest module of the chelated-metal transport system, whereas nicotianamine synthase appeared much later through horizontal gene transfer from fungi. YSL-mediated transport therefore functioned at first without nicotianamine, implying the ancestral use of alternative siderophores, and canonical Strategy II appears to have arisen by exaptation of this pre-existing system, coinciding with an expansion of YSL genes in Poaceae (de Campos et al. 2026, preprint).
More broadly, we ask how ancestral transporters and signaling proteins with broad or poorly specialized activities were recruited into more specific roles, and how nutrient acquisition systems became linked to the ecological expansion of plants on land.
Gene family evolution and neofunctionalization
Gene families are the raw material of evolutionary innovation. We reconstruct the origin, duplication history and functional divergence of gene families involved in protein quality control, oxidative stress, development and defense, in plants and across eukaryotes. Examples include:
- the calreticulin and calnexin chaperone families of green plants, whose founder genes duplicated in early tracheophytes, giving rise to groups of orthologs with specialized functions (Del Bem 2011);
- the ascorbate peroxidase-related (APX-R) and ascorbate peroxidase-like (APX-L) families, whose origin involved the progressive deterioration of ascorbate-binding and catalytic sites towards neofunctionalization, revealed by hybrid proteins in basal Archaeplastida (Lazzarotto et al. 2021);
- the ADAM metalloprotease family, which we traced to the last common ancestor of eukaryotes through its presence in early-branching green algae, with major expansion in early vertebrates and early loss in green plants (Souza et al. 2020);
- the origin and evolutionary history of defense-related proteins in plants, reviewed in a book chapter (Pires et al. 2024);
- stress-responsive families with agronomic relevance, such as the superoxide dismutases of castor bean seeds germinating under water restriction and the WRKY transcription factors of cacao responding to witches’ broom disease.
These projects connect deep evolutionary reconstruction to plant physiology, development and stress biology, including the regulation of cell proliferation during flower development and the integration of hormone and sugar signals by transcription factors such as the Arabidopsis bZIP protein AtbZIP63.
Genome architecture, non-coding RNAs and epigenetic variation
Genomes are much more than collections of protein-coding genes. They also contain regulatory sequences, repetitive elements, transfer RNAs, small and long non-coding RNAs and multicopy gene families. We study how these components evolve and how they relate to genome size and biological complexity.
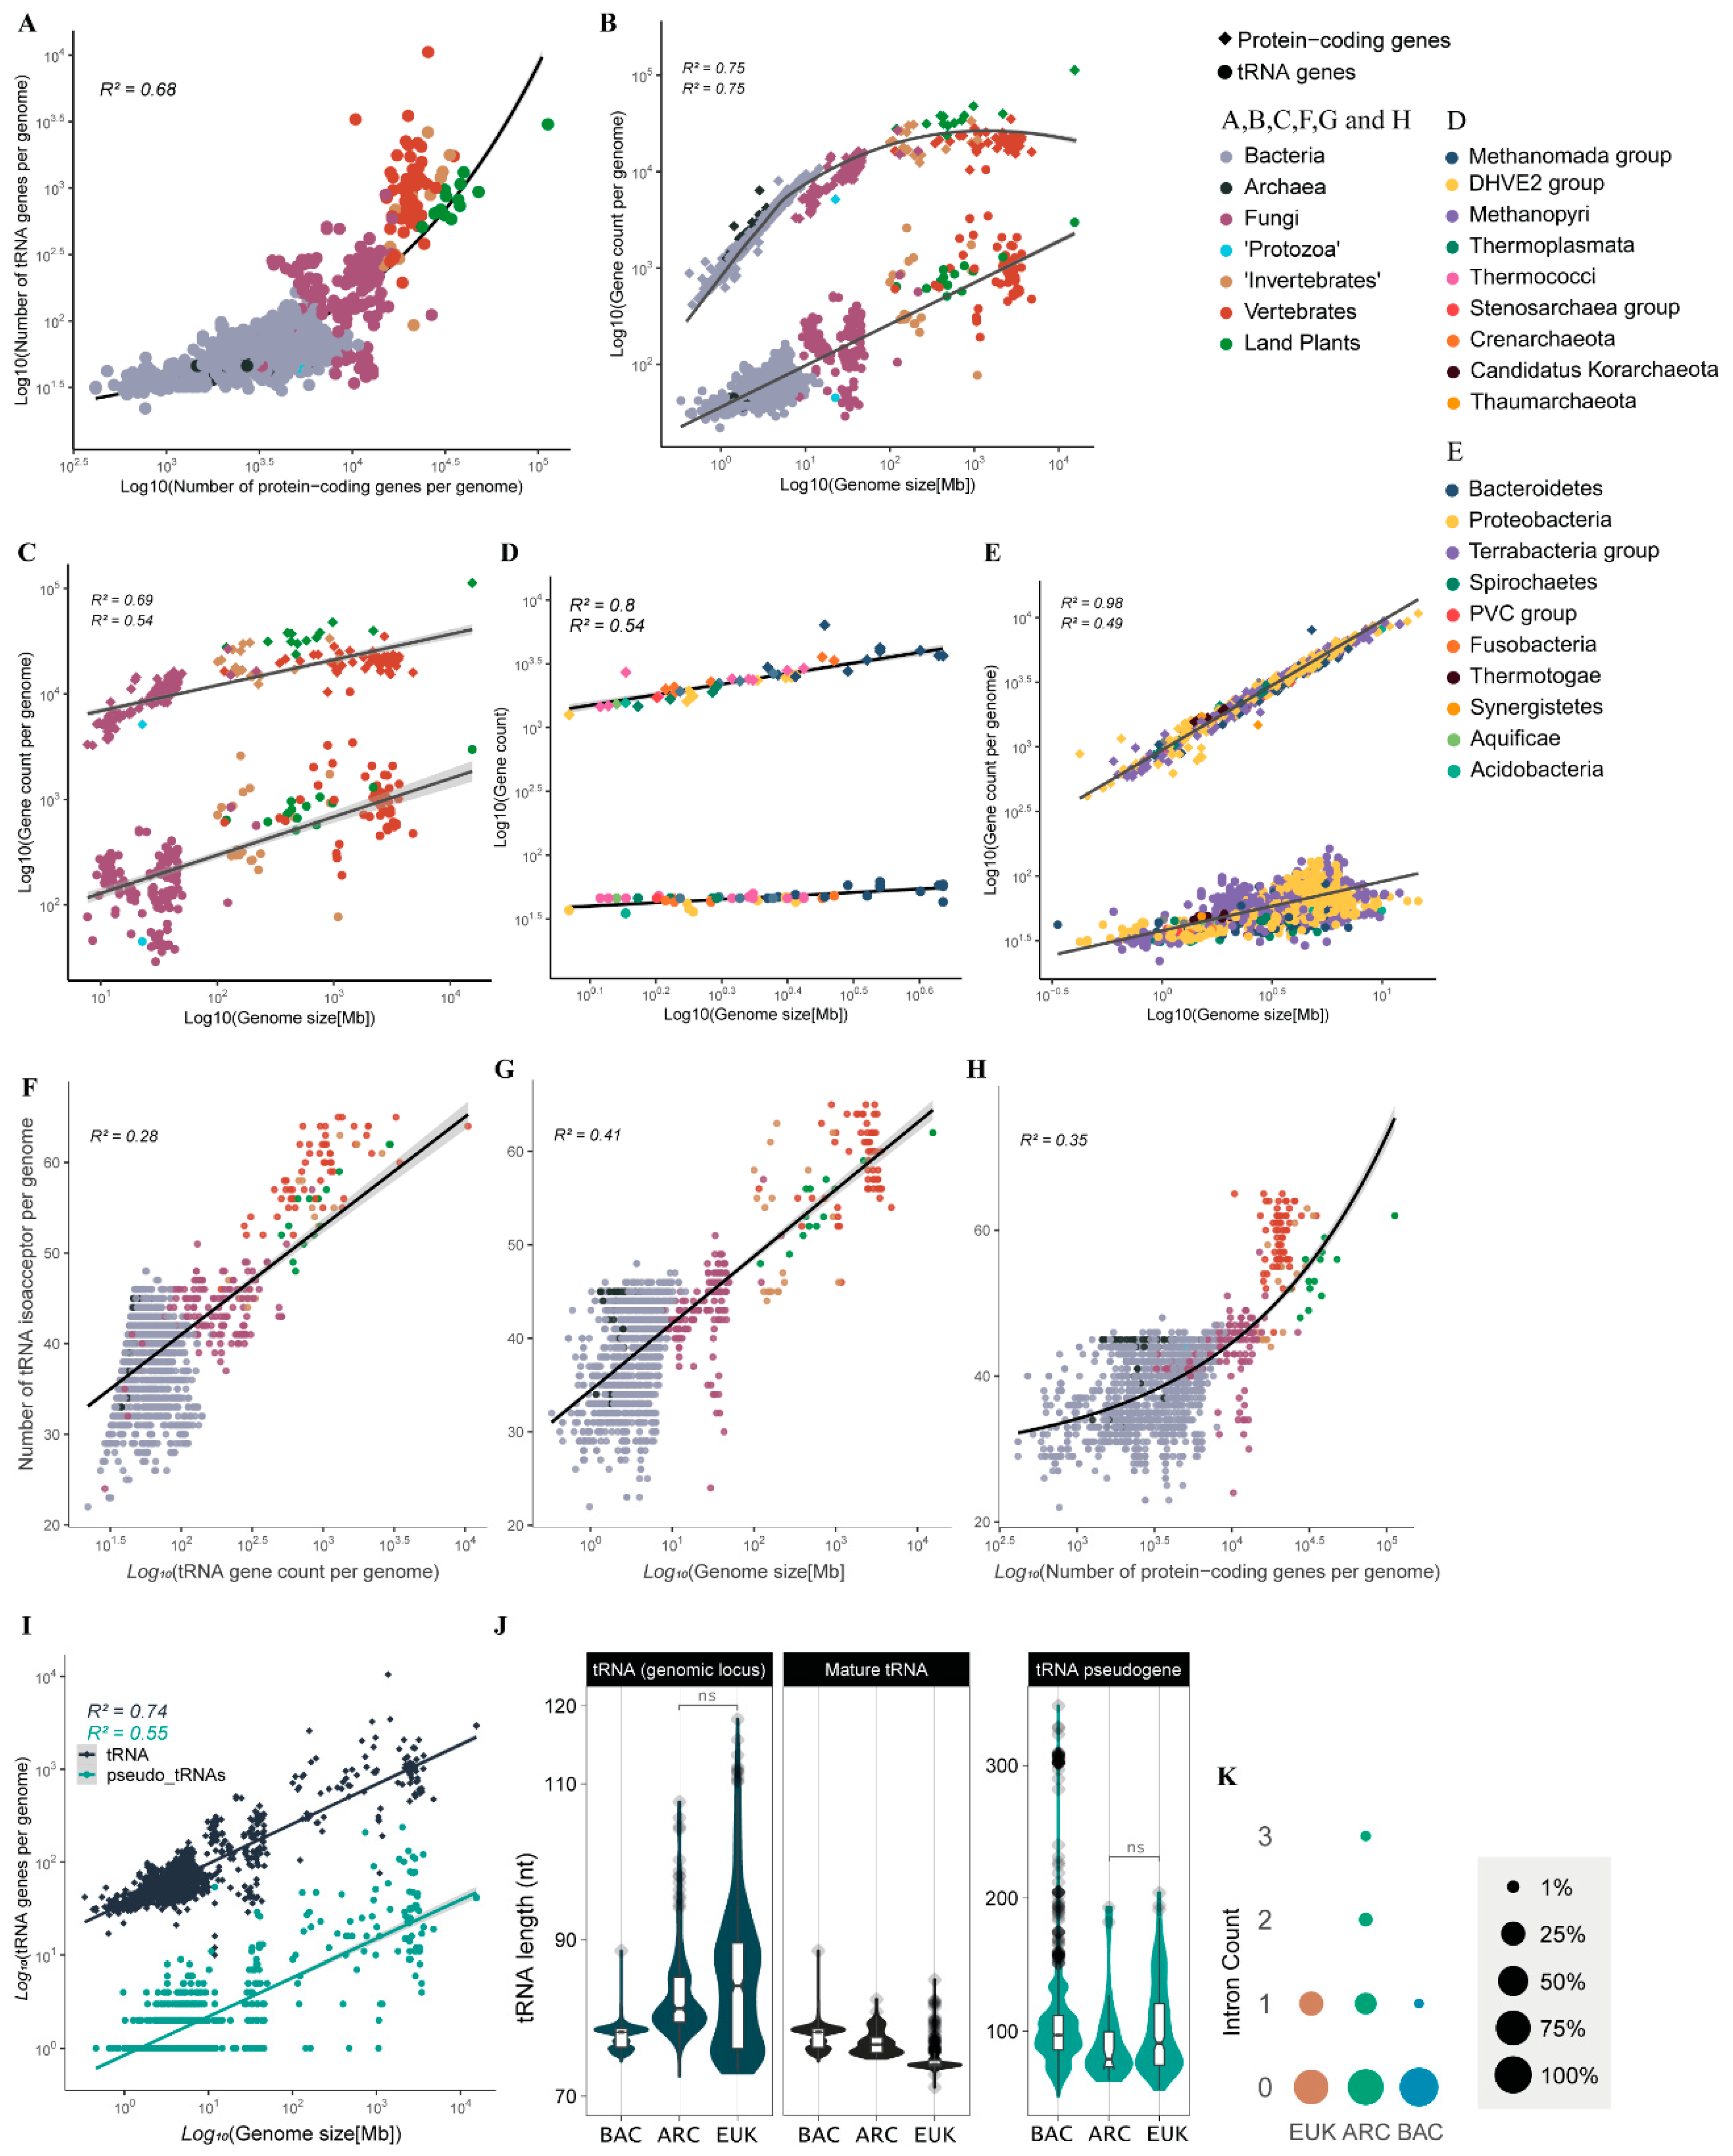
Analyzing thousands of genomes from the three domains of cellular life, we showed that tRNA copy number is largely controlled by genome size in all cellular organisms, in contrast to protein-coding genes, which stop expanding between roughly 20,000 and 35,000 loci per haploid genome in eukaryotes regardless of genome size. Changes in the tRNA gene pool accompanied the bacteria/archaea split and eukaryogenesis, and macroscopic eukaryotes with many cell types, such as land plants and vertebrates, independently evolved a high diversity of anticodons together with high gene redundancy (Santos & Del-Bem 2023).
Related projects in this area include:
- Genome size in land plants. Using phylogeny-aware comparative methods, we searched for protein domain families whose abundance correlates with genome size variation, recovering domains related to nucleotide metabolism, DNA repair and genome organization, including the histone H2A superfamily, which is more frequent in larger genomes and may help preserve their stability (Menezes et al. 2022, preprint).
- De novo genes and epigenetic variation. The recently originated Arabidopsis thaliana gene QQS shows extensive natural variation in expression that correlates negatively with DNA methylation of repeats at its 5′ end, and both can be inherited over generations without DNA sequence changes, suggesting that young genes may be particularly prone to epigenetic variation (Silveira et al. 2013).
- Non-coding RNAs. From microRNAs and conserved non-coding RNAs in sugarcane to long non-coding RNAs across nine hemi-, holo- and endoparasitic plant species, where lncRNA repertoires vary with the degree of parasitism and show elevated activity in the haustorial tissues of Cuscuta (Rodrigues et al. 2024, preprint).
Crop genomes: sugarcane and bioenergy plants
Genomics of crops, particularly those relevant for bioenergy, has been part of our trajectory from the beginning. We contributed to early efforts to identify sugarcane genes associated with sucrose content, to the identification and expression analysis of its microRNAs, to the discovery of thousands of missing coding genes and conserved non-coding RNAs in sugarcane ESTs, and to building the sugarcane genome for biotechnology.
By sequencing and analyzing homo/homeologous genomic regions of the highly polyploid sugarcane genome, we found that these loci retain strong collinearity with sorghum and rice but were invaded by transposable elements, that all haplotypes appear functional yet contribute unequally to gene expression, and that Saccharum officinarum and S. spontaneum diverged between 2.5 and 3.5 million years ago, with evidence for independent polyploidization events in the lineage that gave rise to S. officinarum (Vilela et al. 2017).
We have also characterized the transcriptome of the oil-rich seed of the bioenergy crop Jatropha curcas and the seed proteome of castor bean (Ricinus communis), connecting genomic resources to traits of agronomic interest.
Viral genome evolution: giant viruses, phages and SARS-CoV-2
Viruses provide extreme examples of how genomes expand, reorganize and generate new functional repertoires. In collaboration with virologists at the Federal University of Minas Gerais and other groups, we study the genomics and evolution of giant viruses, bacteriophages and human pathogens.
- Gene duplication and giant genomes. The description of cedratvirus pambiensis, which has the largest genome reported for a cedratvirus, showed that its size can be attributed to an unprecedented number of duplicated genes. Extending the analysis to other viruses pointed to gene duplication as a key mechanism driving genome expansion in diverse giant viruses (Machado et al. 2023, Journal of Virology).
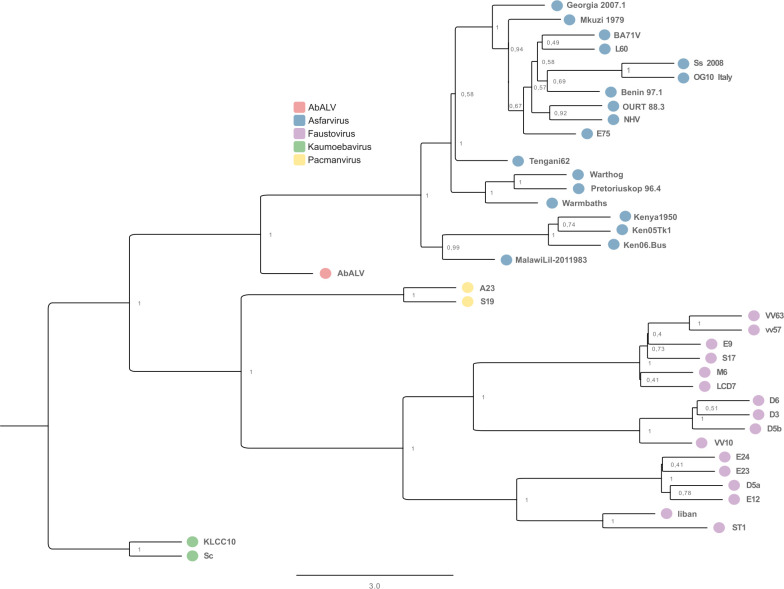
- Taxonomy of the extended Asfarviridae. By integrating comparative genomics, pangenomics and phylogenomics across 39 complete genomes, we showed that African swine fever virus, faustoviruses, kaumoebaviruses, pacmanviruses and the abalone asfar-like virus are deeply divergent lineages that form multiple families rather than one, and we proposed demarcation criteria and a formal reclassification of the clade. The group has an open pangenome with a core of only 37 genes, underlining how much of its diversity remains unexplored (Mendonca-Santos, Abrahao & Del-Bem 2025, Journal of Virology, Editor’s Pick).
- Vault proteins in bacteriophages. Searching viral protein databases, we identified the first major vault proteins described in viruses, in tailed bacteriophages from human gut metagenomes. Phylogenetic and structural analyses place them close to bacterial homologs and raise the question of what role they play in phage biology (Santos et al. 2023, preprint).
- SARS-CoV-2 and the host. We modelled how natural variation in the human ACE2 receptor affects its binding affinity to the Spike protein of different SARS-CoV-2 genotypes (Santos et al. 2022), and analyzed isoform-level expression in infected human cells, finding that infection is associated with the predominant expression of unproductive splicing isoforms of interferon signaling, class I MHC and splicing machinery genes, while cytokine genes keep expressing productive isoforms (Dias et al. 2024).
Organelle genomes: the dynamic mitochondria of fungi
Mitochondrial genomes are compact but surprisingly variable, which makes them excellent models for studying how non-coding elements shape genome architecture. Together with collaborators at UFMG and other institutions, we have characterized fungal mitogenomes at several scales.
A survey of hundreds of curated fungal mitogenomes revealed size differences of up to 260 kb, driven mainly by the number and length of accessory elements such as introns, homing endonuclease genes and unidentified open reading frames. Remarkably, no single gene is shared by all the mitogenomes analyzed, which complicates their use as universal taxonomic markers (Fonseca et al. 2021). In Agaricomycetes, accessory genes are shared between distantly related species, most likely through horizontal transfer, whereas unidentified ORFs are shared mainly among closely related taxa, consistent with vertical inheritance (Araujo et al. 2021). In Hypocreales, mitogenome length correlates strongly with the number and size of non-coding sequences, and introns and homing endonuclease genes emerge as key elements shaping these genomes (Fonseca et al. 2020).
Computational tools and genomic resources
Comparative genomics on this scale requires tools and curated data, and we take part in building them. With the Lobo Lab (UFMG) we contributed to CALANGO, a phylogeny-aware comparative genomics tool that finds homologous regions and biological roles associated with quantitative phenotypes across species, addressing the statistical problem created by shared ancestry. In two case studies it recovered both known and previously unidentified genotype-phenotype associations, including a link between maximum height in angiosperms and the expansion of a reproductive mechanism that prevents inbreeding (Hongo et al. 2023, Patterns).
We also contributed to ARCADE (ARChaeplastida Annotation DatabasE), a database of high-quality non-redundant archaeplastidian proteomes gathered from several primary genomic databases, together with proteome quality metrics and associated metadata, designed to support statistically sound comparative analyses (Menezes et al. 2022, preprint).
Day to day, our work relies on phylogenetic inference and orthology assignment, large-scale annotation pipelines, pangenomics, protein structure modelling and molecular dynamics, statistical modelling and phylogeny-aware comparative methods, applied to public genomic databases and to data generated with our collaborators. The goal is not only to describe gene families, but to infer the evolutionary processes that shaped them and to generate testable hypotheses about biological function.
Our broader goal
The broader goal of the Del-Bem Lab is to understand how genomes generate biological complexity. We are especially interested in the evolutionary events that changed the trajectory of life on Earth: the origin of plant terrestriality, the diversification of cell wall systems, the assembly of nutrient acquisition pathways, the emergence of new regulatory layers, the expansion of genome architecture, and the repeated invention of molecular functions through duplication, transfer and repurposing.
We work in a highly collaborative way, with partners in plant biology, virology, mycology, biochemistry, structural biology, bioinformatics and biomedical research in Brazil and abroad. A full list of our articles and preprints, with links to the original publications, is available on the Publications page. If you are interested in joining the lab, please see Join us.